126.8K+
TOTAL FARE RECORDS PROCESSED

Moove US Used City-Level Ride-Hailing Fare Data Scraping for Advanced Mobility Pricing, Competitive Benchmarking, and Urban Transportation Intelligence
This case study is based on a real-world enterprise mobility intelligence scenario in which a transportation analytics team uses structured data extraction to collect, normalize, compare, and analyze city-level ride-hailing fare information associated with Moove US operations. The objective is to transform fragmented fare observations into a structured intelligence layer covering trip prices, distance, duration, vehicle categories, pickup locations, time periods, and market-level pricing movements.
The project demonstrates how Moove US Used City-Level Ride-Hailing Fare Data Scraping can support transportation companies, mobility analysts, aggregators, researchers, and pricing teams that require consistent visibility into fare behavior across individual US cities.
It is designed for:
The client's core requirement was to build a scalable system capable of transforming continuously changing ride-hailing fare observations into structured city-level records. Instead of relying on isolated manual checks, the organization wanted a consistent data foundation that could support fare benchmarking, historical comparisons, market research, route-level analysis, and dynamic pricing intelligence.
The system therefore focused on Ride-hailing fare data scraping Across Asia, Africa & Europe comparable fare observations across selected cities and organizing them according to route, date, time, distance, duration, vehicle type, and observed price.
A recent mobility intelligence initiative examined how structured city-level fare data could help transportation businesses understand pricing behavior across the US ride-hailing ecosystem. The project used Moove US city-level data Analysis to organize fare observations into comparable records across selected metropolitan markets, trip categories, routes, and time periods.
The analytical framework captured fare values, estimated trip duration, route distance, vehicle category, pickup area, destination area, timestamp, and market identifiers. These records were then normalized to ensure that similar journeys could be compared despite differences in city geography, trip distance, traffic conditions, and vehicle availability.
The initiative also focused on Ride-hailing price monitoring across international markets, creating a broader analytical framework that could compare US observations with pricing intelligence from other global mobility markets. This allowed analysts to identify market-specific pricing behaviors while maintaining consistent measurement standards.
The client used structured datasets to evaluate average fares, fare-per-mile, fare-per-minute, price ranges, surge-related movements, route-level differences, and time-of-day patterns. Instead of analyzing individual prices in isolation, the organization could examine how pricing changed across comparable city-level trip scenarios.
The resulting intelligence environment supported dashboards, benchmarking models, pricing reports, and historical trend analysis. Analysts could identify cities with higher average ride costs, markets with greater fare volatility, and routes where pricing changed significantly during particular periods.
The client operated in a rapidly changing mobility environment where ride-hailing prices can vary considerably according to city, route, demand, time, vehicle category, traffic conditions, and availability. Traditional manual price collection could provide individual observations but could not efficiently produce a consistent historical dataset for large-scale analysis.
One of the biggest challenges was creating consistent Asia, Africa & Europe ride-hailing pricing intelligence alongside US market observations. Different cities have different fare structures, currencies, trip characteristics, and transportation conditions, making direct comparison difficult without standardized data fields and analytical methodologies.
Another major requirement involved Global ride-hailing fare benchmarking using city-level data. The client needed to compare average fares, route economics, price-per-distance, and price volatility at the city level instead of relying only on national or platform-wide averages.
The organization also needed reliable Ride-hailing API data Scraping capabilities to support structured collection and downstream analytics. A fragmented approach made it difficult to maintain consistent records across large numbers of routes and time periods.
The client therefore required a structured mobility data pipeline that could continuously capture ride-hailing fare observations, standardize the records, and prepare them for analytical applications.
By implementing an automated city-level fare intelligence framework, the client replaced fragmented manual price checks with a structured process for collecting and analyzing ride-hailing pricing observations.
The system continuously organized fare information by city, route, vehicle category, distance, duration, timestamp, and observed price. This allowed analysts to compare equivalent trip scenarios and identify market-level pricing patterns.
| Dimension | Manual Ride-Hailing Tracking | Client Data Scraping System |
|---|---|---|
| Data collection | Individual fare checks across selected routes | Automated collection across large route and city combinations |
| Market coverage | Limited number of cities | Expanded city-level US market coverage |
| Price monitoring | Periodic manual observations | Continuous structured fare observations |
| Route analysis | Basic route-by-route comparison | Normalized origin-destination analysis |
| Historical intelligence | Scattered spreadsheets and records | Centralized historical fare database |
| Fare benchmarking | Limited sample comparisons | City, route, category, and distance-based benchmarking |
| Price volatility | Difficult to quantify | Historical price movement and volatility analysis |
This structured approach gave the client a repeatable framework for converting individual fare observations into a larger mobility intelligence dataset.
The brand in focus is a mobility-focused transportation organization operating across urban markets and requiring granular visibility into ride-hailing economics. Its analytical environment covers city-level transportation behavior, trip pricing, route characteristics, vehicle categories, and changing fare conditions.
As its market intelligence requirements expanded, the organization needed greater visibility into how ride-hailing fares behaved across individual US cities. National averages were not sufficient because transportation markets differ substantially by geography, trip density, traffic patterns, consumer behavior, and operating conditions.
The organization therefore adopted a city-level data intelligence framework centered on Moove US fare observations.
The objective was not simply to collect prices. Instead, the organization wanted to understand the relationship between price, distance, duration, city, route, vehicle type, and time period.
The resulting system allowed analysts to investigate questions such as:
This shift from simple price collection to structured mobility intelligence significantly expanded the analytical value of the data.
We delivered an end-to-end mobility analytics solution designed to transform raw ride-hailing fare observations into structured, comparable, and analysis-ready datasets.
The first layer focused on collecting fare observations across selected US cities and predefined trip combinations. Each observation was associated with standardized fields such as city, pickup location, destination, vehicle category, estimated distance, estimated duration, fare, timestamp, and market identifier.
The system was designed to Track Dynamic Ride-Hailing Prices by capturing changing fare observations across different time periods. Instead of treating price as a static attribute, the analytical framework treated it as a time-sensitive market signal.
The second layer focused on data normalization. Duplicate observations were removed, inconsistent city names were standardized, distance and duration fields were normalized, and fare values were converted into comparable analytical formats.
The solution incorporated Mobile App Data Scraping Services to support mobility datasets generated through app-based transportation ecosystems. The resulting records were organized into structured tables suitable for dashboards, statistical analysis, historical comparisons, and machine learning applications.
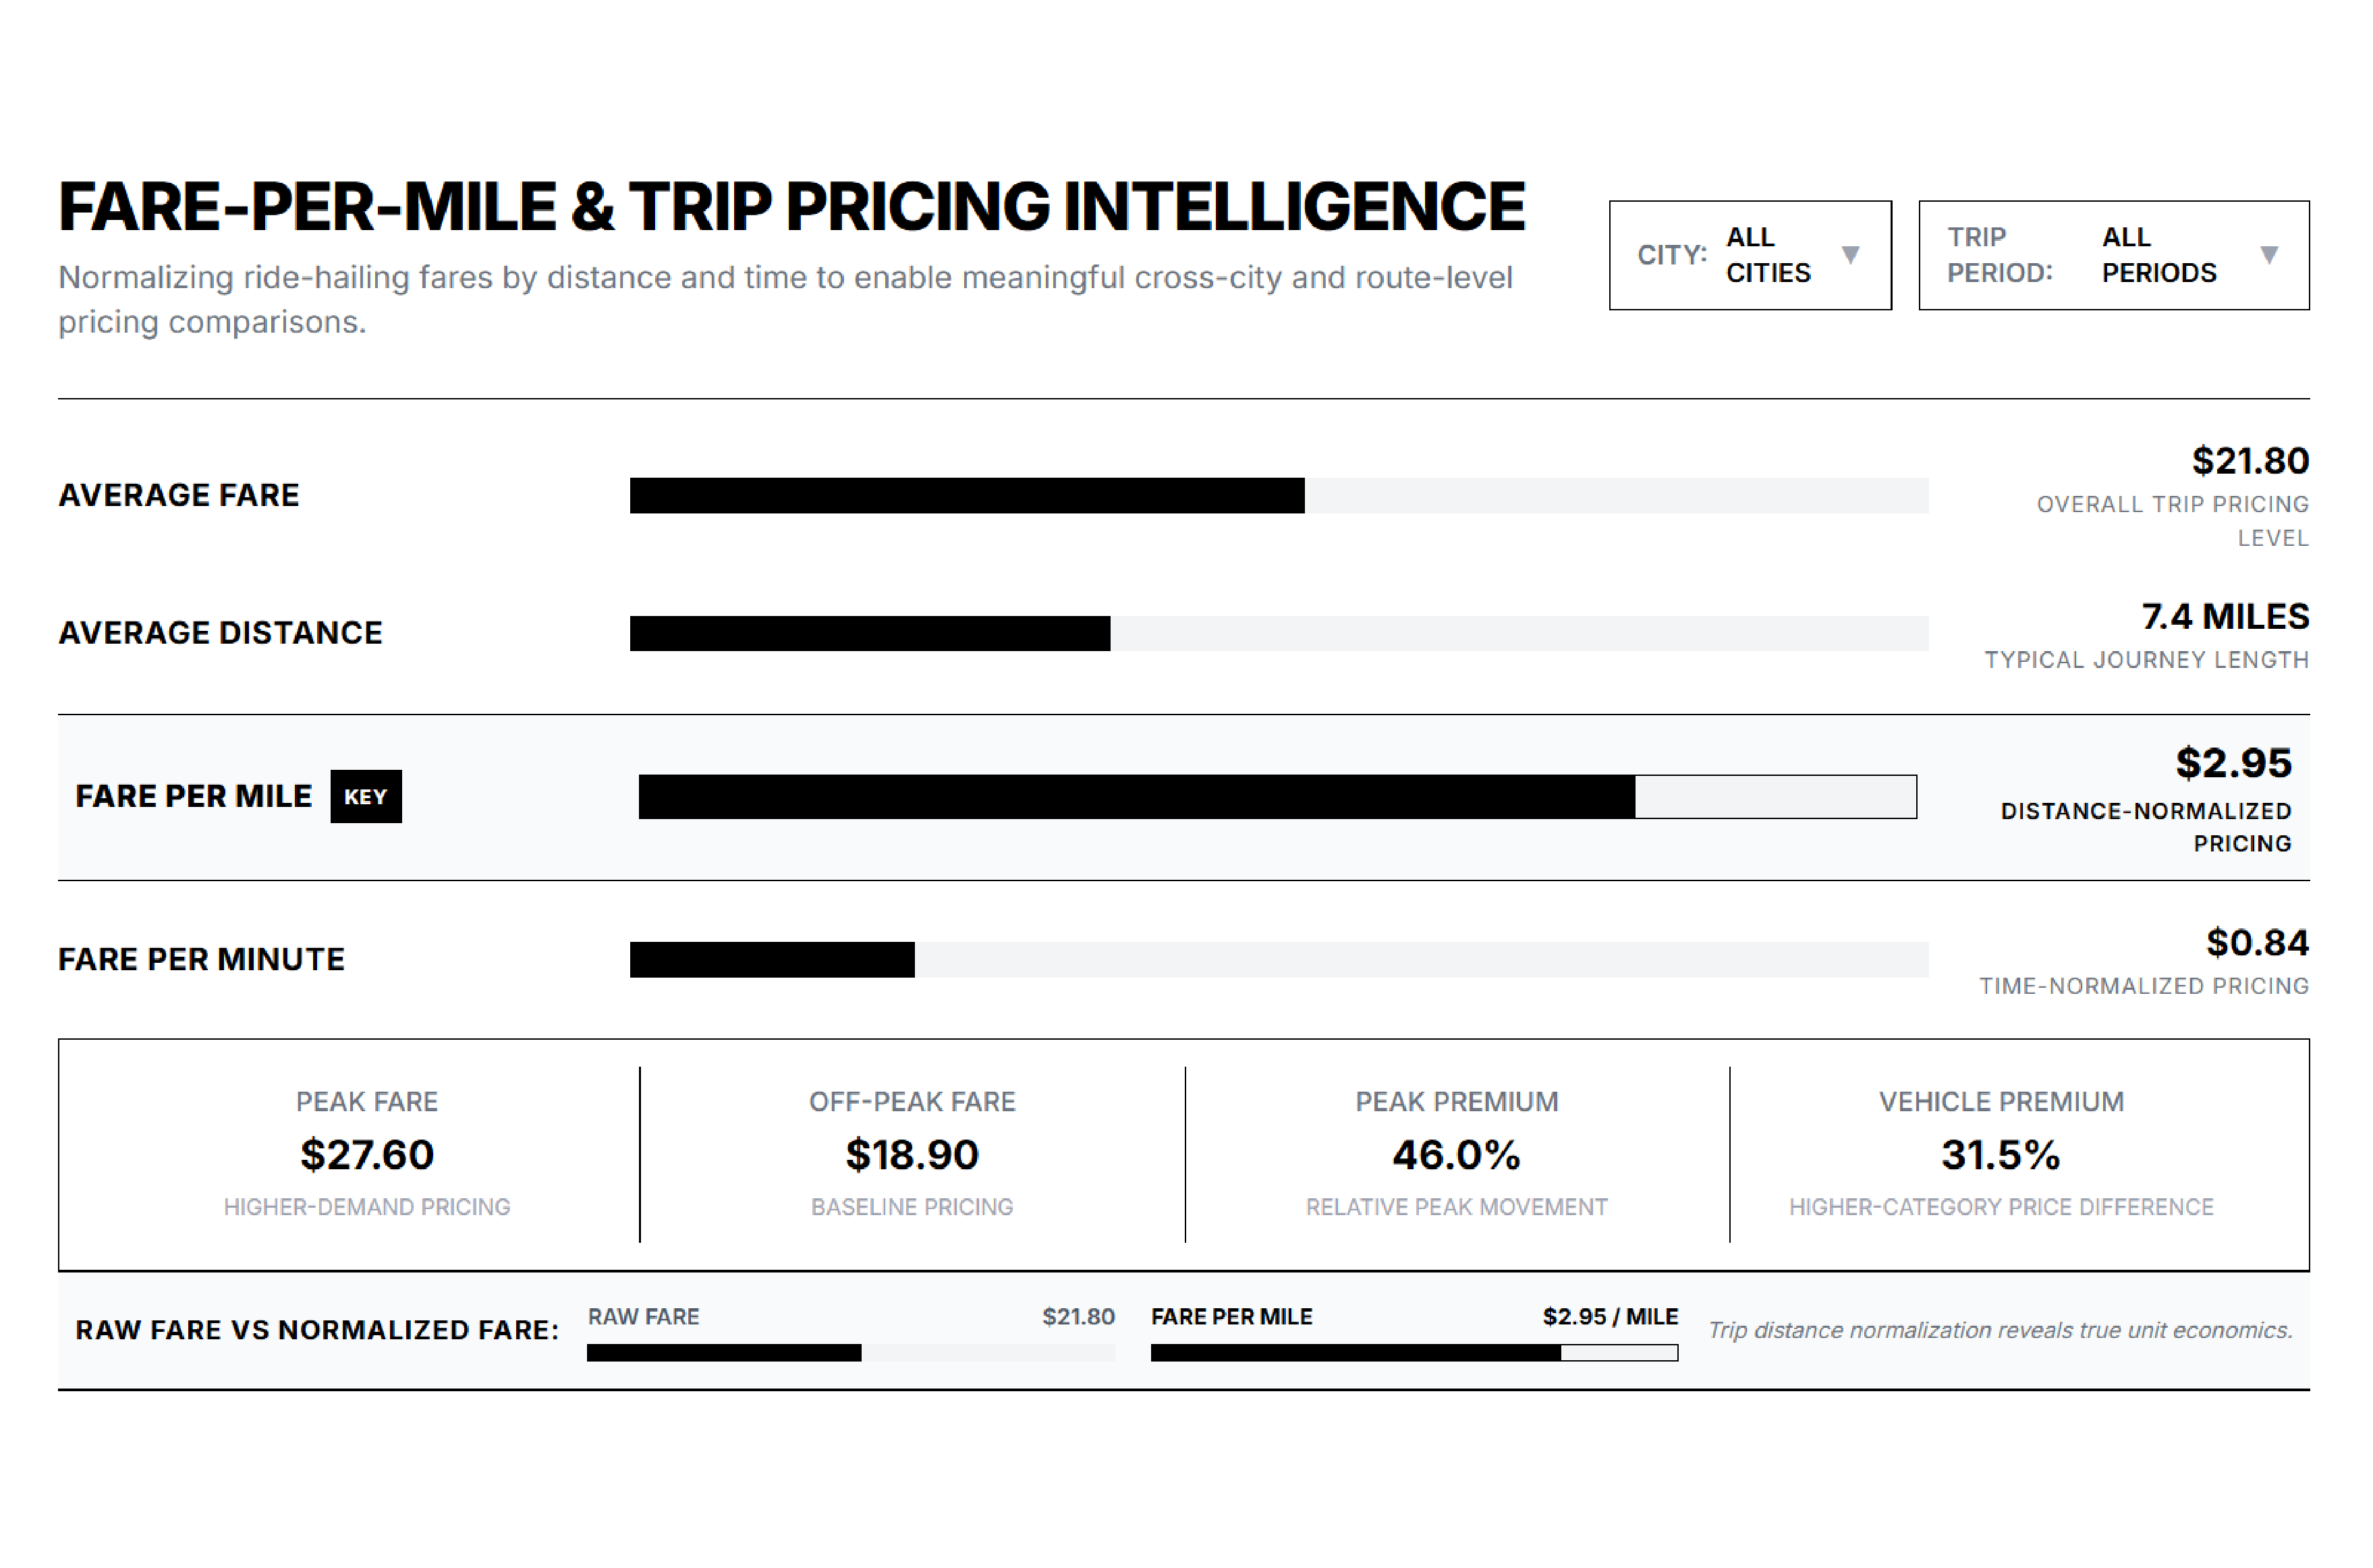
One of the strongest findings was that ride-hailing prices varied considerably between city-level markets even when comparable trip distances were analyzed.
A standardized trip scenario demonstrated that raw fare alone was insufficient for understanding market economics. Analysts therefore evaluated fare alongside distance and duration.
Markets with higher absolute fares did not necessarily have the highest fare-per-mile. Some cities demonstrated longer average trip distances, while others showed higher pricing intensity across shorter urban journeys.
This distinction helped the client develop more accurate city-level benchmarks.
The analysis also demonstrated the value of grouping observations into comparable trip bands. Instead of comparing every trip individually, the system could group journeys by distance ranges such as 1–3 miles, 3–5 miles, 5–10 miles, and 10+ miles.
This improved the consistency of cross-city benchmarking.
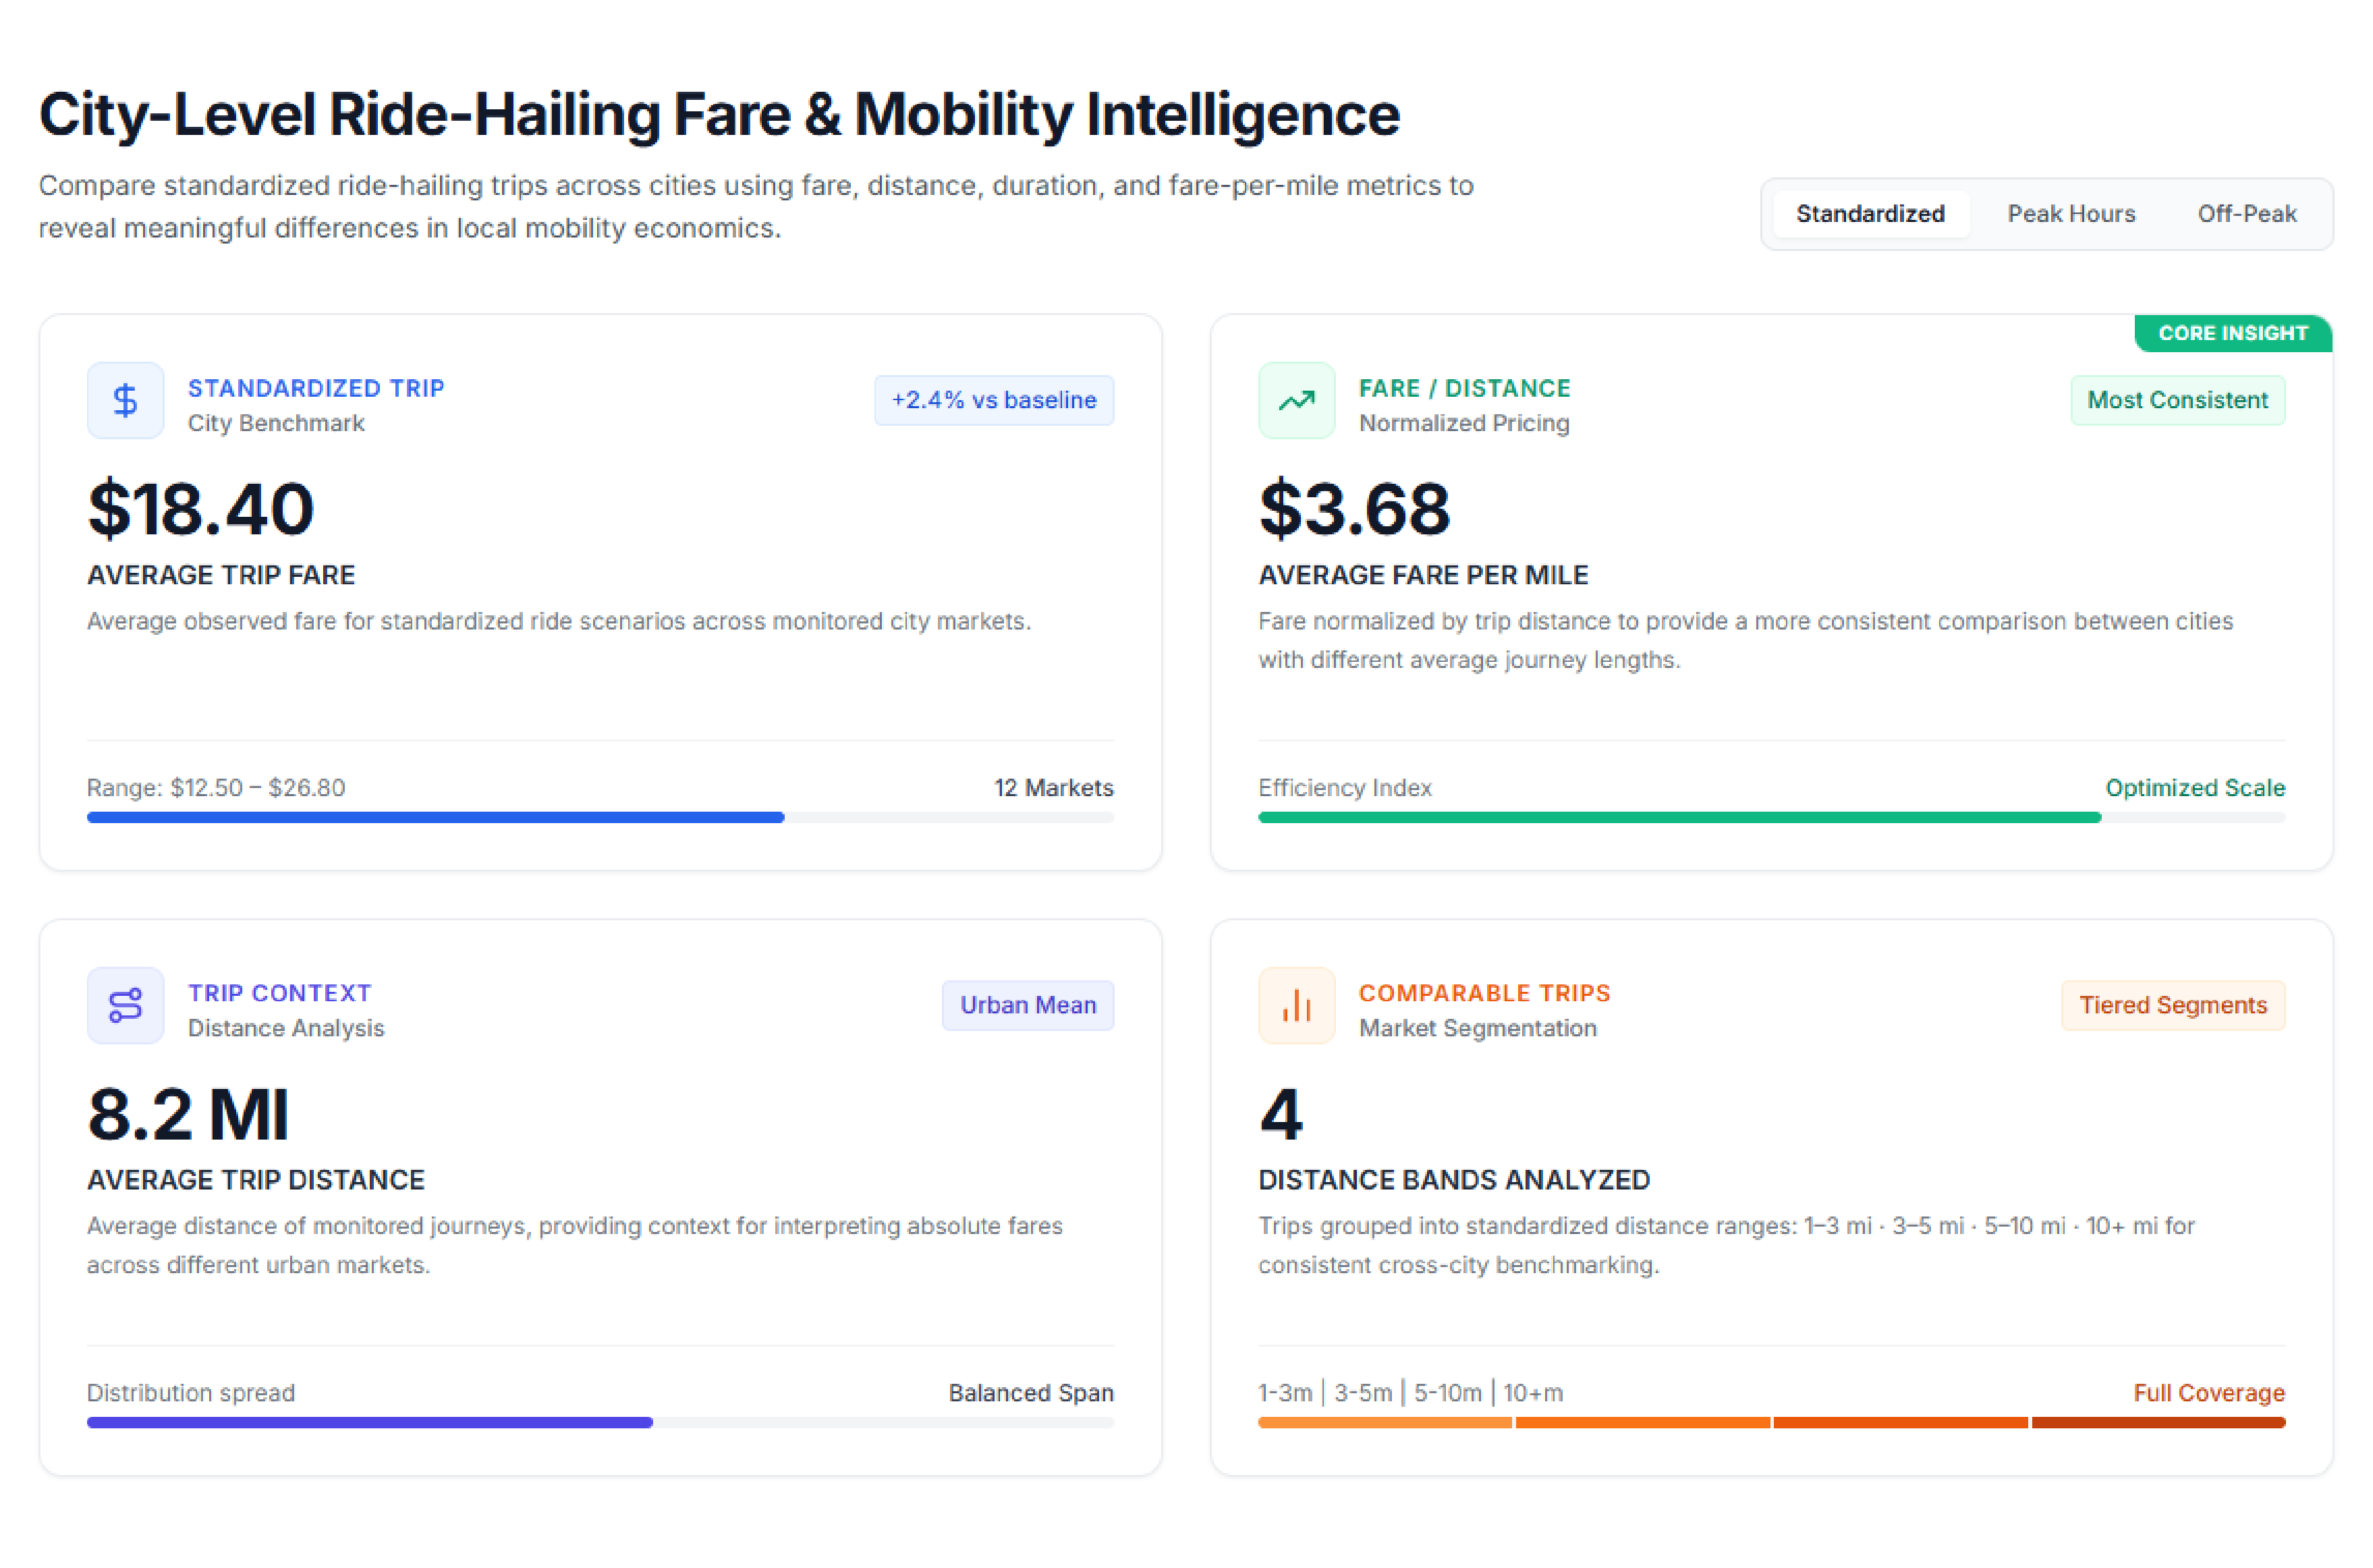
The second major finding involved time-dependent fare behavior.
Morning and evening periods demonstrated higher pricing activity across several monitored markets compared with selected off-peak periods. However, the intensity of movement differed by city.
The structured dataset allowed analysts to calculate:
Instead of relying on general assumptions about surge periods, the client could identify actual historical patterns from structured observations.
This supported better understanding of how urban demand affected fare behavior.
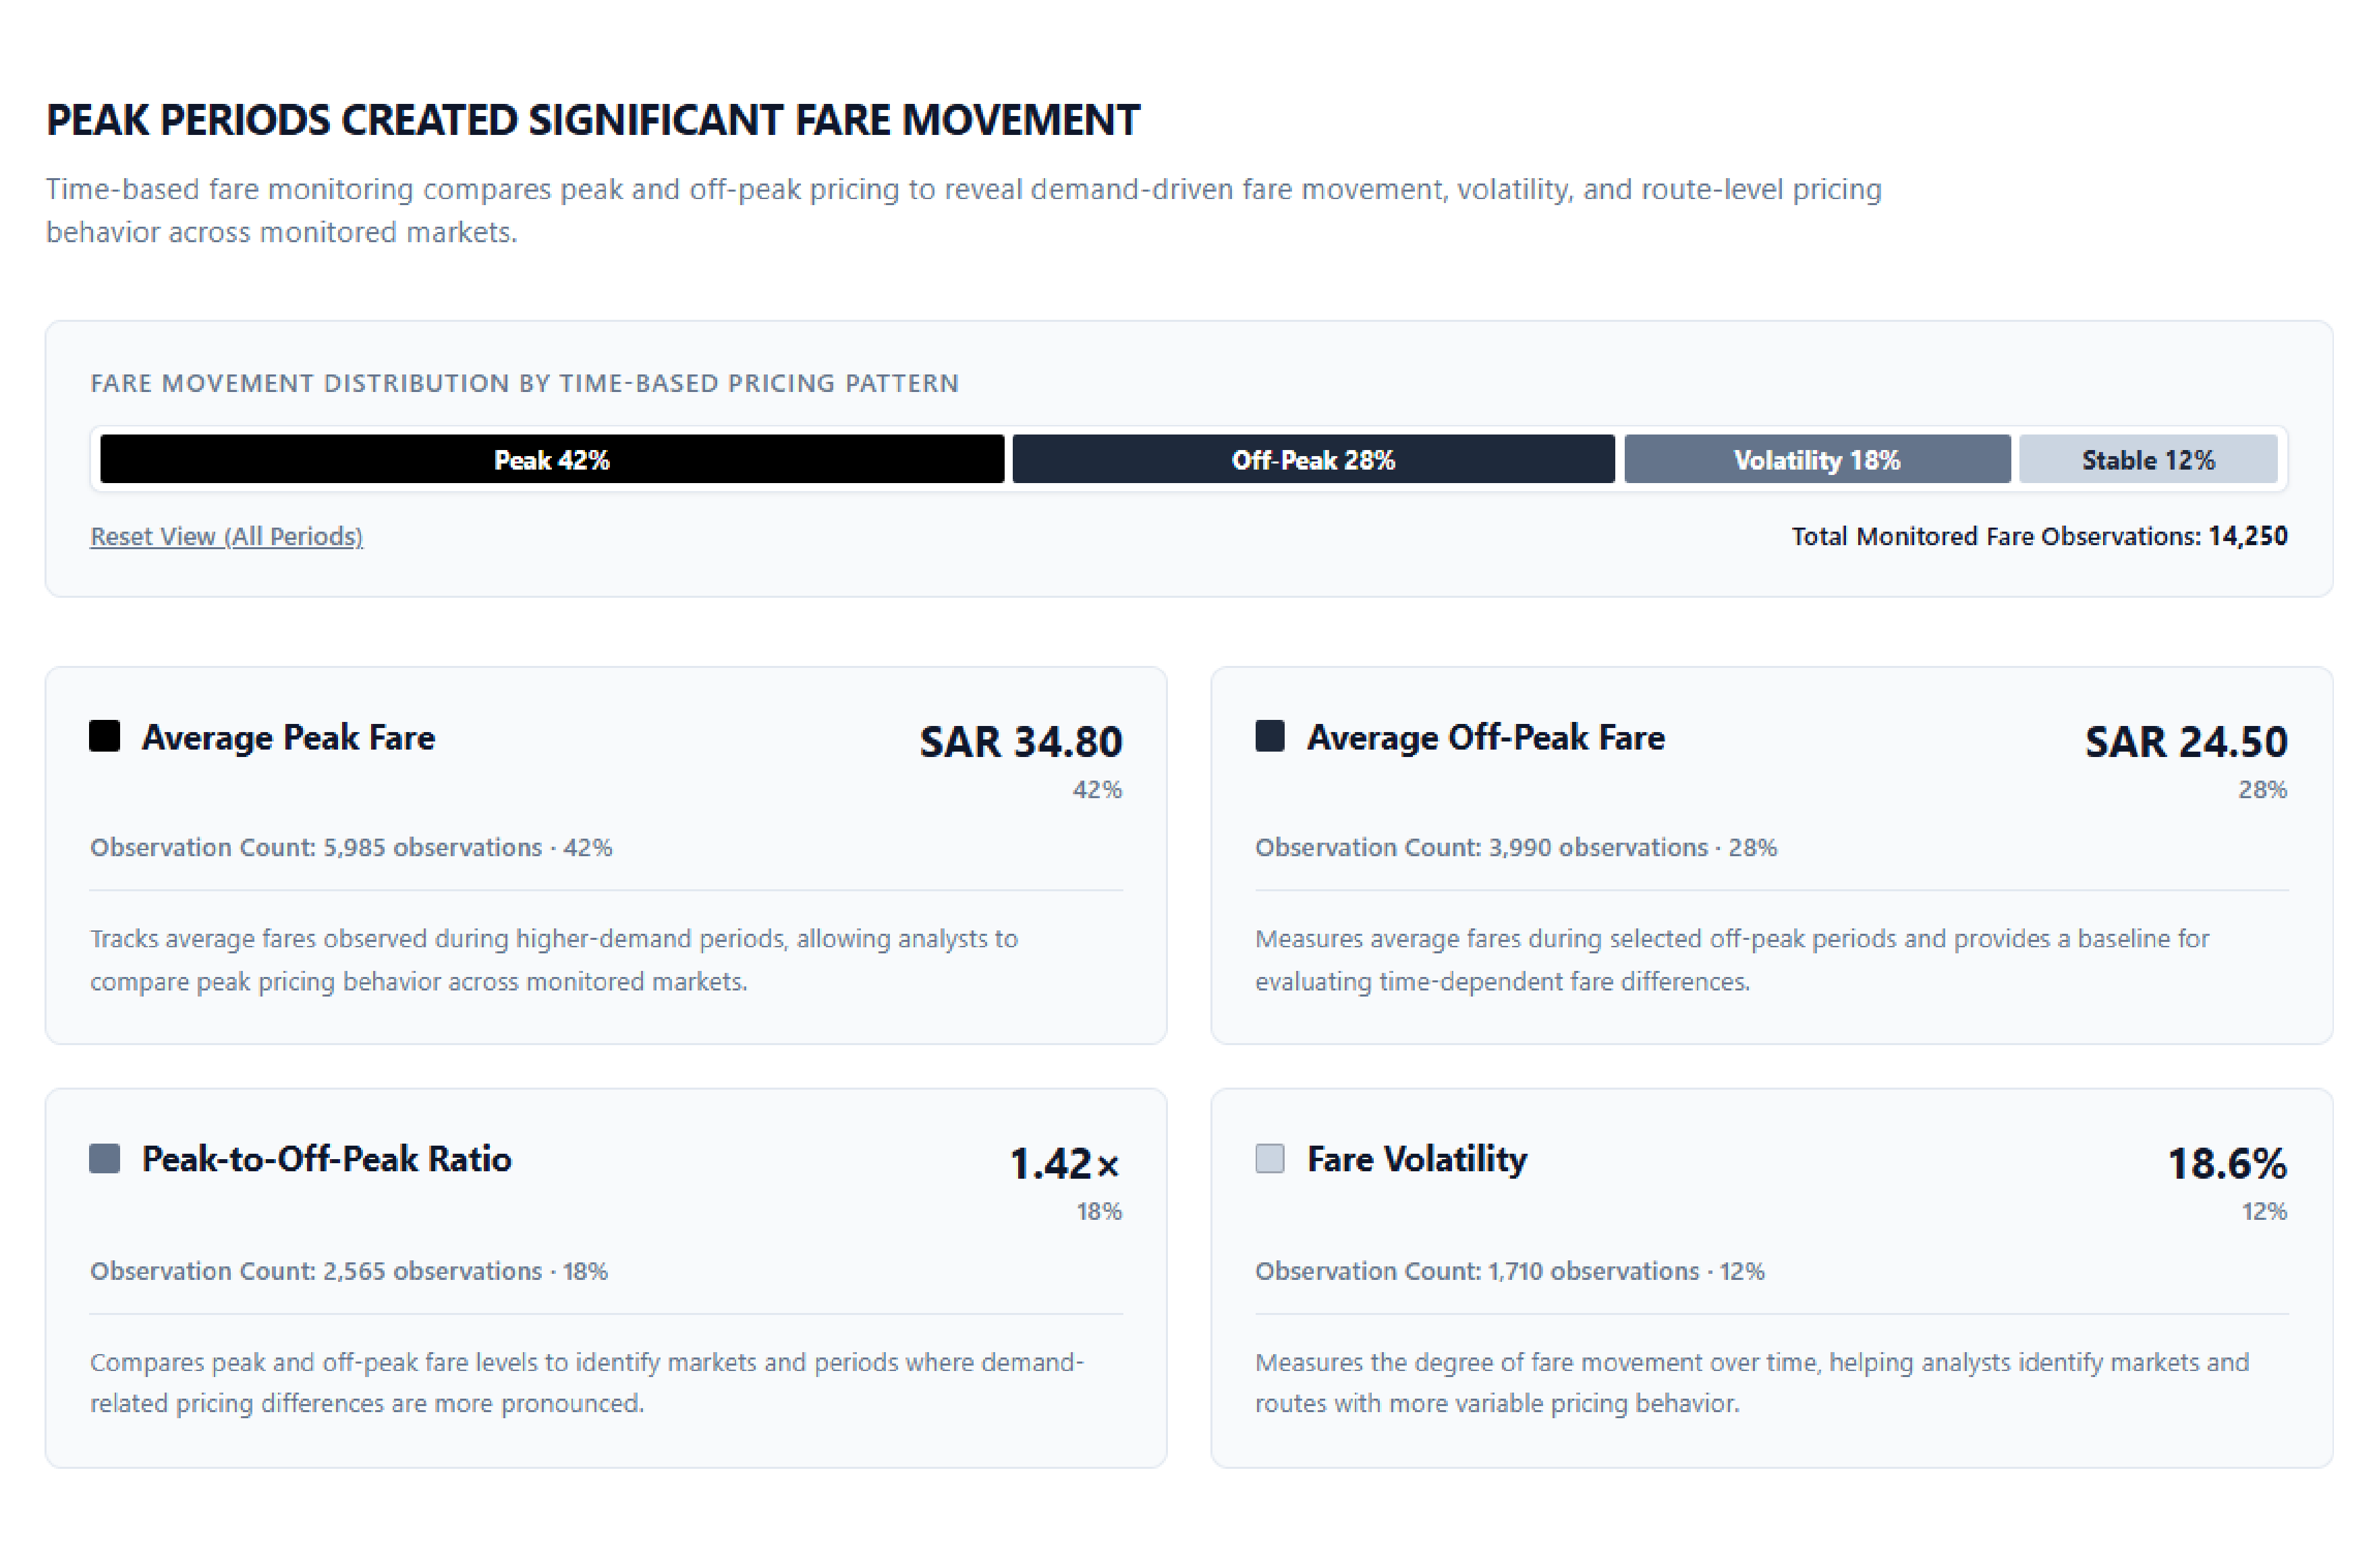
A major analytical improvement came from calculating fare-per-mile.
Raw fare comparisons can be misleading when trip lengths differ. A $30 fare may represent a reasonable price for a long-distance journey but a significant premium for a short urban trip.
The system therefore calculated fare-per-mile for each observation and aggregated the results by city, route, vehicle category, and time period.
| Metric | Sample Observation | Business Interpretation |
|---|---|---|
| Average Fare | $21.80 | Overall trip pricing level |
| Average Distance | 7.4 miles | Typical journey length |
| Average Duration | 26 minutes | Estimated trip time |
| Fare per Mile | $2.95 | Distance-normalized pricing |
| Fare per Minute | $0.84 | Time-normalized pricing |
| Peak Fare | $27.60 | Higher-demand pricing |
| Off-Peak Fare | $18.90 | Baseline pricing |
| Peak Premium | 46.0% | Relative peak movement |
| Fare Range | $12.40–$41.80 | Observed pricing spread |
| Vehicle Premium | 31.5% | Higher-category price difference |
This normalization allowed the client to compare markets using more meaningful economic indicators.
The following dataset snapshot illustrates how structured city-level ride-hailing fare records can be organized for analytical use.
| City | Vehicle Type | Avg Fare | Distance | Duration | Fare/Mile | Peak Fare | Off-Peak Fare | Sentiment/Market Signal | Price Volatility |
|---|---|---|---|---|---|---|---|---|---|
| Atlanta | Standard | $19.80 | 6.8 mi | 22 min | $2.91 | $25.40 | $17.10 | Stable Demand | 21.4% |
| Austin | Standard | $21.60 | 7.1 mi | 24 min | $3.04 | $28.30 | $18.20 | Rising Demand | 27.8% |
| Chicago | Standard | $24.90 | 7.5 mi | 29 min | $3.32 | $33.70 | $20.10 | High Demand | 34.6% |
| Dallas | Standard | $20.70 | 7.9 mi | 25 min | $2.62 | $26.90 | $17.80 | Stable Demand | 24.1% |
| Houston | Standard | $19.40 | 8.2 mi | 27 min | $2.37 | $25.20 | $16.90 | Moderate Demand | 23.5% |
| Los Angeles | Standard | $27.80 | 8.4 mi | 32 min | $3.31 | $38.40 | $22.60 | High Demand | 39.2% |
| Miami | Standard | $23.50 | 7.0 mi | 26 min | $3.36 | $31.80 | $19.90 | Rising Demand | 31.7% |
| Phoenix | Standard | $18.90 | 7.6 mi | 23 min | $2.49 | $24.70 | $16.20 | Stable Demand | 22.6% |
| Seattle | Standard | $25.70 | 6.9 mi | 28 min | $3.72 | $34.20 | $21.40 | High Demand | 36.8% |
| Washington DC | Standard | $26.40 | 6.5 mi | 30 min | $4.06 | $35.80 | $21.90 | High Demand | 38.5% |
The sample illustrates why city-level ride-hailing intelligence requires multiple analytical dimensions. A market with a high average fare may also have longer trip distances, while another city may demonstrate higher fare-per-mile despite a lower average trip price.
After implementing the structured city-level ride-hailing intelligence system, the client achieved significant improvements in pricing visibility, market comparison, and transportation analytics.
Our approach enables mobility businesses to convert fragmented ride-hailing observations into structured, reusable datasets that can support pricing analytics, route benchmarking, market research, forecasting, and strategic planning.
The system is designed around data consistency. City names, routes, vehicle categories, distances, durations, timestamps, and fare values are standardized so that analysts can compare records without repeatedly cleaning the underlying data.
Another important advantage is historical intelligence. By maintaining structured fare observations over time, businesses can move beyond one-time price checks and evaluate pricing trends, volatility, and recurring market patterns.
The framework also supports scalable monitoring. As additional cities, routes, vehicle categories, or time periods are introduced, the data architecture can expand without requiring a complete redesign of the analytical workflow.
Data validation further improves reliability by identifying duplicates, incomplete records, inconsistent values, and anomalous observations before information reaches downstream dashboards.
We are extremely satisfied with the mobility data intelligence solution delivered by the team. The project gave us a much clearer view of ride-hailing pricing across individual city markets and helped us move away from fragmented manual price checks.
The structured datasets made it easier to compare fares by route, distance, duration, vehicle category, and time period. We were particularly impressed by the ability to identify pricing movements and historical patterns that were difficult to observe through manual monitoring.
The solution has significantly improved our reporting speed and market benchmarking capabilities. Our analysts can now work with consistent, organized data instead of spending large amounts of time preparing raw observations.
The dashboards and analytical datasets have strengthened our ability to evaluate transportation markets, identify pricing opportunities, and make faster strategic decisions.
—Head of Mobility Intelligence
The final outcome of the project was a scalable city-level ride-hailing intelligence environment capable of converting continuously changing fare observations into structured mobility datasets.
The client achieved significantly stronger visibility into fare behavior across US urban markets. Instead of analyzing isolated price observations, stakeholders could evaluate pricing through multiple dimensions, including city, route, distance, duration, vehicle category, and time period.
Integration of Automotive data scraping capabilities further expanded the analytical foundation by creating opportunities to connect mobility pricing intelligence with broader transportation and automotive datasets.
The implementation also established a scalable scraping API layer for supporting structured data delivery into downstream analytical environments, dashboards, reporting systems, and data warehouses.
A structured ride-hailing dataset can include city, pickup location, destination, vehicle category, fare, estimated distance, estimated duration, timestamp, and other relevant market attributes. These fields can then be normalized for pricing analysis and benchmarking.
City-level analysis provides more granular market intelligence than national or platform-wide averages. Different cities can have significantly different fare levels, trip distances, traffic conditions, demand patterns, and pricing volatility.
Historical fare observations can be grouped by city, route, time period, distance, and vehicle category. This allows analysts to identify pricing movements, peak-period differences, volatility, and unusual changes.
Yes. Standardized fare datasets can be used to compare pricing levels, fare-per-mile, fare-per-minute, route economics, vehicle category premiums, and market-level price movements across selected transportation markets.
Yes. A structured data architecture can be expanded to additional cities, routes, vehicle categories, and observation periods. This makes the system suitable for organizations building large-scale mobility intelligence datasets.
Our data scraping and analytics solutions help transform dynamic transportation pricing into structured datasets, enabling faster benchmarking, deeper market visibility, and smarter mobility decisions at scale.
Start a projectFields marked * are required. Everything else just helps us scope faster — skip what you don't know yet.